How Can QA Teams Improve Software Testing Outcomes?
Software testing strategies work best when they tell the team where quality risk is highest, which checks should run early, and what evidence is enough before release. Start with the workflows that would hurt users or the business most if they failed, then choose testing levels, environments, automation, and reporting around those risks.
How testing levels fit into your strategy
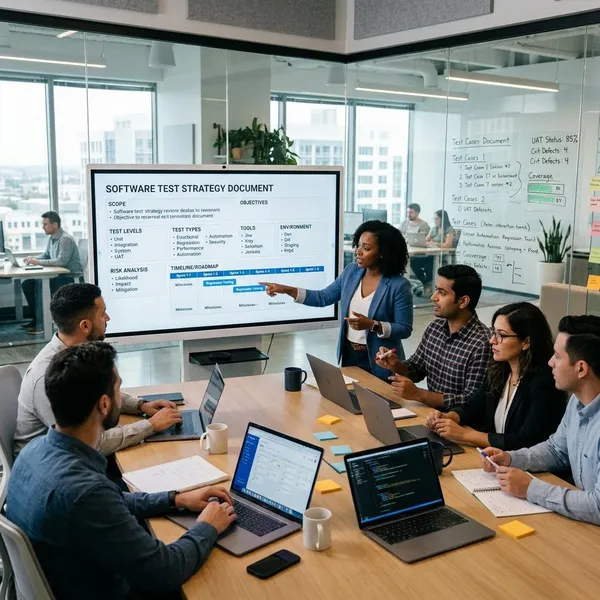
Testing levels give your strategy a practical structure. Unit tests catch small logic problems early, integration tests check connections, system tests prove full workflows, and acceptance tests confirm whether the software is actually ready for business use.
Unit testing for individual components
Unit testing checks small pieces of logic in isolation, usually before the feature reaches a broader QA cycle. It is most useful for rules that can be verified quickly, such as price calculations, validation rules, permission checks, date handling, or data transformations.
If a team releases often, weak unit testing usually shows up as noisy regression work later. Strong unit tests do not prove the whole product works, but they stop simple defects from travelling into integration and system testing, where they become slower to diagnose.
Integration testing for connected components
Integration testing answers a different question: do the parts still work when they talk to each other? This is where API contracts, database calls, authentication services, payment gateways, message queues, and third-party tools need attention.
- Prioritize shared boundaries: APIs, service contracts, data formats, and authentication handoffs.
- Test failure paths: timeouts, rejected responses, duplicate requests, and missing data.
- Use realistic data: simple mock values can hide mapping or permission problems.
System testing for complete workflows
System testing checks the complete application through realistic user journeys. It should focus on workflows that matter most, such as registration, checkout, account recovery, report generation, or order processing.
Because system tests are slower and more fragile than lower-level checks, more is not always better. A small set of stable, business-critical system tests is usually more useful than a large suite that breaks every time the UI changes.
Acceptance testing for business requirements
Acceptance testing decides whether the product is ready from a business or user point of view. A feature can be technically correct and still fail acceptance if it does not support the real workflow, approval rule, reporting need, or customer expectation.
Use acceptance testing as a release decision point, not as a place to discover basic technical defects. For example, a finance dashboard should already be stable before business users check whether totals, filters, export formats, and approval steps match their actual process.
What should a software test strategy include?
A software test strategy should explain how the team will protect quality across the project, not just how one release will be tested. It should be clear enough to guide everyday choices: what gets tested first, what can be lighter, what needs automation, and what evidence is needed before release.
The strategy sets direction; a test plan handles execution for a specific sprint, feature, or release. If the document cannot help someone make a testing decision under time pressure, it is probably too vague.
Testing objectives and scope
Testing objectives should be specific enough to shape decisions. "Improve quality" is too broad. "Reduce payment failures before release" or "verify supported browser behavior for account signup" gives the team something usable.
Scope should also say what is not being tested. That matters when deadlines tighten. If checkout, password reset, and public APIs are in scope, but an unfinished analytics module is not, stakeholders can understand both the test evidence and the remaining risk.
Risks and priorities
Risk and priority decide where the deepest testing belongs. A low-traffic settings screen rarely deserves the same effort as login, billing, personal data handling, or a workflow used by every customer.
| Area | Testing priority | Reason |
|---|---|---|
| Payments, authentication, personal data | High | Failure can affect revenue, trust, security, or compliance. |
| Core user journeys | High to medium | Frequent use makes even small defects visible quickly. |
| Admin tools and reports | Depends on business impact | Some are internal convenience features; others drive decisions. |
| Cosmetic or rarely used options | Lower | Still worth checking, but usually after critical paths. |
Testing types and levels
The strategy should name the testing types the project actually needs. That may include unit, integration, system, acceptance, regression, API, performance, security, usability, compatibility, or accessibility testing.
Test environments and data
Test results are only as trustworthy as the environment and data behind them. If the environment is unstable, missing services, or very different from production, the team may waste time on false failures or miss real ones.
- Environment checks: services, browsers, devices, permissions, integrations, and configuration.
- Data checks: user roles, edge cases, regional rules, failed states, and realistic volumes.
- Protection checks: masked, synthetic, or safely generated data when sensitive information is involved.
Automation and manual testing plans
Automation and manual testing should not compete. Automation is best for repeatable checks that need fast feedback, while manual testing is better for exploration, judgment, usability, and new behavior that is still changing.
Good automation candidates include smoke tests, API checks, stable regression paths, and build verification in a CI/CD pipeline. Poor candidates include one-time checks, highly subjective visual reviews, and unstable flows that would need constant script maintenance.
Entry and exit criteria
Entry criteria define when testing is ready to begin. Useful checks might include approved requirements, a deployed build, available test data, stable environments, and completed developer-level checks.
Exit criteria define when testing has enough evidence to support a release decision. These may include passed critical tests, no open blocker defects, reviewed known issues, and stakeholder agreement on acceptable residual risk.
Defect tracking and reporting
Defect tracking should make problems easier to act on, not just easier to count. The strategy should define severity, priority, ownership, retesting expectations, and escalation paths.
- Severity: how serious the defect is for users or the system.
- Priority: how soon it should be fixed.
- Ownership: who investigates, fixes, retests, and closes it.
- Reporting: what stakeholders need to know before a release decision.
How to build a software testing strategy
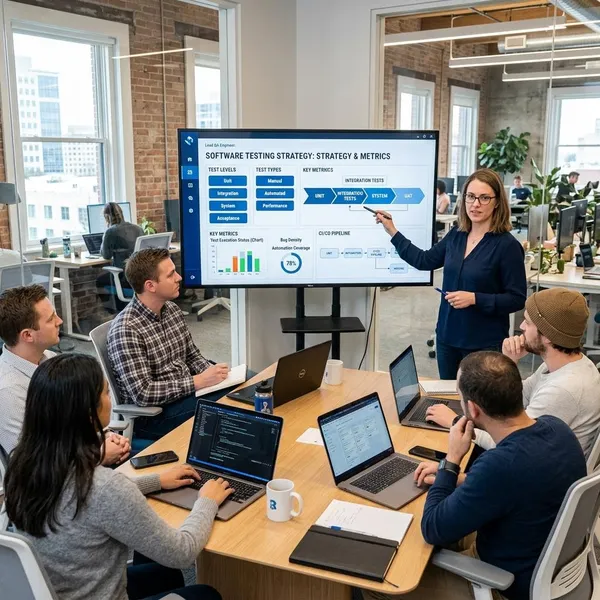
Build the strategy by starting with quality goals, then mapping risks, testing approaches, automation, environments, data, and release criteria around those goals. Keep it practical: the team should be able to use it during sprint planning, release discussions, and defect triage.
A startup shipping twice a week will need a different rhythm from a regulated healthcare platform preparing a controlled release. Both need a strategy, but the level of formality, evidence, and documentation will not be the same.
Define your quality goals
Start by deciding what quality means for this product. For one team, it may mean no critical defects in checkout. For another, it may mean accurate reporting, stable performance during peak hours, or strict access control for sensitive data.
Identify high-risk areas
List the areas where failure would cause the most damage. Look at business impact, user visibility, security exposure, compliance needs, operational disruption, and technical complexity.
Do not judge risk by code complexity alone. Password reset may be technically small, but if it locks out users or creates an account takeover risk, it deserves serious attention.
Choose the right testing approaches
Choose approaches that fit the product's risks and architecture. API-heavy systems usually need strong integration and contract testing. Consumer-facing apps often need more compatibility, usability, and exploratory work. Data-heavy platforms may need careful validation around imports, permissions, transformations, and reports.
Copying another team's testing model is tempting, but it often fails. The better question is: where would a defect hurt most, and which testing approach would catch it earliest with reasonable effort?
Decide what to automate
Automate tests that are valuable, repeatable, stable, and easy to verify. If a check runs on every build or every release and gives a clear pass or fail signal, it is usually a strong candidate.
- Automate first: smoke tests, core regression paths, API validations, and build checks.
- Delay automation: unstable features, one-off tests, and flows still changing every sprint.
- Keep manual: exploratory testing, usability judgment, unclear edge cases, and visual review.
Prepare environments and test data
Prepare environments before testing becomes urgent. Shared environments, missing services, expired credentials, or stale data can slow a release as much as actual defects.
Test data should include normal cases, edge cases, failed states, and different user roles. Simple sample data is fine for early checks, but it should not be the only evidence for release readiness.
Set clear success criteria
Success criteria turn testing results into a release decision. They might include no open critical defects, passed smoke tests, completed high-risk regression coverage, accepted known issues, or agreed performance targets.
Be careful with single numbers such as pass rate. A 98% pass rate means little if the failed tests are checkout, login, or data export. Always connect criteria to risk, not just volume.
Review results and improve the strategy
A strategy should change when the product changes. Review it after major releases, production incidents, recurring defects, architecture changes, new integrations, or a shift in release frequency.
- Escaped defects: show where coverage or risk judgment was weak.
- Flaky tests: reveal automation or environment problems.
- Blocked testing: points to data, access, or ownership gaps.
- Slow feedback: suggests the test mix may not fit the delivery model.
How to choose the right testing strategy
The right testing strategy is the one that fits your application, risk level, release frequency, and team capacity. There is no universal best model. A lightweight internal tool may need a simple risk-based approach, while a banking, healthcare, or logistics platform usually needs deeper evidence and stricter controls.
Consider application complexity
Complex applications usually need broader coverage because defects often appear at boundaries. Microservices, asynchronous processing, third-party APIs, multiple user roles, mobile devices, and heavy configuration all increase the number of places where things can fail.
A simpler app may not need a large testing stack, but it still needs careful checks around its core workflow. A basic invoice tool, for example, can be small and still high impact if the totals are used for real payments.
Prioritize business and technical risks
Business risk should drive test depth. Billing, identity, data privacy, reporting accuracy, and customer-facing workflows usually deserve earlier and stronger validation than low-impact interface details.
Technical risk adds another layer. Legacy code, frequent changes, weak documentation, many dependencies, or fragile deployments are signals that a feature may need extra coverage even if it looks ordinary to users.
Match testing to release frequency
Fast release cycles need fast feedback. If a team ships daily, it cannot rely mainly on slow manual regression at the end. Smoke tests, API checks, automated regression, and clear pipeline gates become much more important.
Slower release cycles can support broader scheduled validation, but they still benefit from automation in stable, high-value areas. The goal is alignment: the testing rhythm should match how quickly the product changes.
Consider available time and resources
A realistic strategy fits the team you actually have. If automation skills are limited, start with a small set of high-value checks instead of trying to automate everything. If test environments are scarce, protect the most important end-to-end flows and strengthen lower-level tests where possible.
Limited resources do not mean careless testing. They mean the team has to be stricter about priority. Do the checks that reduce the largest risk first, then add depth where the product, users, or release model justify it.
Conclusion
A strong testing strategy gives the team a clear order of attention: protect the highest-risk workflows first, use the right testing level for each kind of defect, and define what evidence is enough before release. It does not need to be complicated, but it does need to be honest about risk, time, data, environments, and team capability.