How Do Deep Learning and Machine Learning Compare?
If you are weighing deep learning vs machine learning, start with the shape of your data: structured tables usually point to machine learning, while images, speech, video, and large text problems often point to deep learning. Deep learning is not a rival field; it is a type of machine learning that uses layered neural networks. The practical choice comes down to data volume, compute budget, explainability, and whether humans can reasonably define the important signals.
What is machine learning?
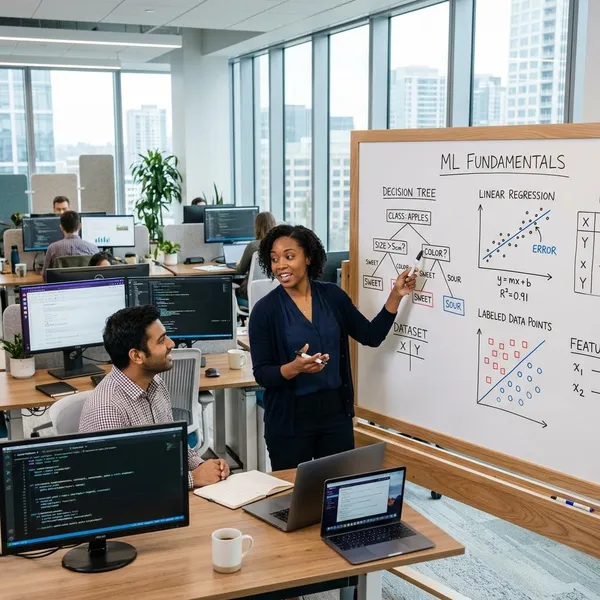
Machine learning is the broader approach: a model learns patterns from examples and then uses those patterns to predict, classify, rank, or recommend something new. It is often the more practical starting point when the data already has structure, such as rows in a spreadsheet, transaction logs, customer records, or sensor readings.
Learns patterns from training data
A machine learning model is trained on examples. If past emails are labeled as spam or not spam, the model looks for signals that separate the two. If past house sales include price, location, size, and condition, the model learns which details tend to affect value.
Uses algorithms to make predictions or decisions
After training, the algorithm turns new input into an output: a price estimate, a fraud score, a product recommendation, a risk category, or a yes/no classification. That makes machine learning useful when you need repeatable decisions from data you already collect.
- Prediction: estimating sales, demand, prices, or energy use.
- Classification: sorting emails, claims, tickets, or transactions into categories.
- Ranking: ordering products, search results, leads, or recommendations.
Often relies on selected or engineered features
Traditional machine learning usually needs people to choose or create the inputs, often called features. For a customer churn model, useful features might include purchase frequency, last login date, support complaints, and subscription age.
Includes models such as trees, regressions, and support vector machines
Common machine learning models include decision trees, regression models, support vector machines, random forests, and gradient boosting methods. A simple regression may be enough for forecasting; a tree-based model may be better when the team wants clearer decision logic.
For a small business predicting monthly demand from past orders and seasonality, a classic model is often faster, cheaper, and easier to maintain than a deep learning setup. Starting simple also gives you a baseline: if a lighter model already works well, the heavier approach may not be worth it.
What is deep learning?
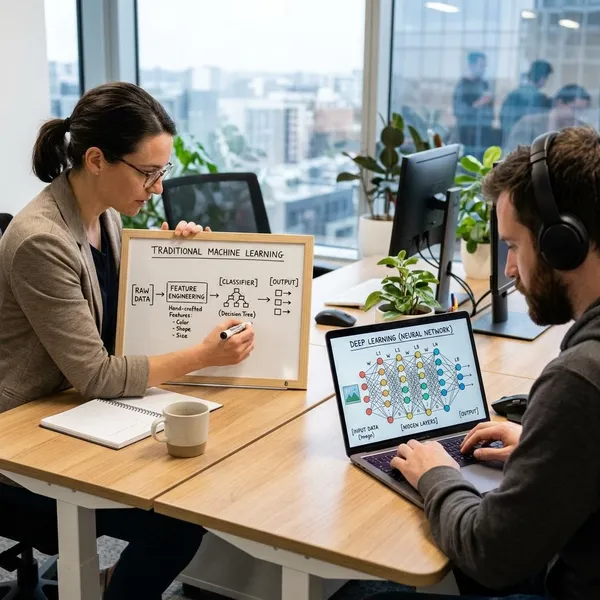
Deep learning is a specialized branch of machine learning built around neural networks with many layers. Those layers allow the model to learn simple patterns first and combine them into more complex patterns later, which is why deep learning is so strong with raw, messy, high-dimensional data.
Uses multi-layer neural networks
A deep learning model passes data through multiple layers. In an image system, early layers may notice edges or contrast, middle layers may detect shapes, and later layers may recognize objects such as faces, cars, or road signs.
That layered design is powerful, but it also makes the model harder to inspect. You may know the model performed well on a test set without being able to explain every internal step in plain business terms.
Learns complex features from data
Deep learning reduces the need to hand-design every feature. Instead of telling the system exactly which visual clues, sound patterns, or word relationships to watch for, you train it on enough examples and let the network learn useful representations.
This is helpful when the important signal is difficult to describe. A person can list some signs of a damaged product in a photo, but a deep model may learn subtle combinations of texture, shadow, angle, and shape that are hard to write as rules.
Handles images, audio, text, and other complex inputs
Deep learning is usually the stronger choice for unstructured inputs: photos, video, voice recordings, scanned documents, free-form text, and similar data that does not fit neatly into columns. A voice assistant, for example, has to handle accent, speed, background noise, and context at the same time.
Includes architectures such as CNNs and transformers
Deep learning is not one single model. Different architectures are built for different kinds of patterns:
- CNNs: commonly used for images and video because they capture local visual patterns well.
- Sequence models: useful for ordered data such as time series, speech, or earlier language systems.
- Transformers: widely used for text, search, summarization, translation, and modern generative AI.
The architecture matters because a model that works well for image recognition is not automatically the right tool for text ranking or audio transcription.
Key differences between machine learning and deep learning
The biggest differences are practical rather than theoretical. Machine learning is usually easier to start, cheaper to train, and easier to explain. Deep learning usually needs more data and compute, but it can handle patterns that are too complex for manual feature design.
Data type and volume
Machine learning often works well with structured data: customer tables, pricing records, inventory data, financial transactions, and operational logs. Deep learning is usually better for unstructured data such as images, video, speech, and long text.
Volume matters too. A small but clean tabular dataset may support a useful machine learning model. A deep neural network usually needs many more examples, unless you can use a suitable pretrained model and adapt it carefully.
Feature engineering
With classic machine learning, people often spend serious time preparing features. That may mean combining fields, cleaning categories, creating ratios, or turning dates into useful signals such as account age or time since last purchase.
Deep learning can learn many of those signals automatically, especially from raw media and language. The tradeoff is that you give up some control and usually pay with more compute, longer training, and less transparent behavior.
Training time
Machine learning models often train quickly enough for rapid testing. A team can try a few features, compare models, and adjust the approach without waiting days for each experiment.
Deep learning training can take much longer, depending on model size, dataset size, and hardware. If your project needs frequent retraining or fast experimentation, training time can become a real constraint rather than a minor technical detail.
Computing power
Many machine learning projects can run on standard CPUs or ordinary cloud instances. Deep learning commonly benefits from GPUs or specialized accelerators, especially during training.
Model complexity
Machine learning models are often easier to debug because the input features and model behavior are more visible. Deep learning models can contain millions or billions of parameters, which gives them more expressive power but also makes them harder to tune and monitor.
Explainability
Machine learning is usually easier to explain, especially with regression models, decision trees, or carefully constrained models. That matters when decisions affect credit, insurance, healthcare, hiring, pricing, or compliance.
Performance on complex tasks
Deep learning tends to win when the task depends on subtle patterns in raw input: recognizing objects in images, understanding speech, translating text, generating language, or finding meaning across long documents.
| Project situation | Usually start with | Why |
|---|---|---|
| Clean customer, sales, finance, or operations tables | Machine learning | Fast to test, easier to explain, often accurate enough |
| Images, video, speech, or large text collections | Deep learning | Better at learning complex patterns from raw inputs |
| Small dataset with high need for auditability | Machine learning | Lower risk of overfitting and easier review |
| Large dataset where manual features fail | Deep learning | Can learn richer representations automatically |
When deep learning is the better choice
Deep learning is worth considering when the input is complex, the dataset is large enough, and the extra accuracy or capability justifies the cost. It is not the default answer for every AI problem; it is the better tool when simpler models cannot capture the patterns you need.
When you work with images or video
Images and video contain variation that is hard to describe manually: lighting, angle, distance, motion, background clutter, and image quality all change the signal. Deep learning handles this well because it can learn visual patterns across many examples.
When you work with speech or audio
Speech and audio problems are difficult because sound changes over time. Accent, pitch, pauses, background noise, microphone quality, and speaking speed can all affect the result.
Deep learning is often the practical choice for transcription, voice assistants, speaker recognition, call analysis, music tagging, and sound event detection. If the task only uses simple audio metadata, such as duration or volume levels, classic machine learning may still be enough.
When you work with large amounts of text
Deep learning, especially transformer-based models, is now central to many large text tasks. It can capture context across sentences, paragraphs, and documents in a way that simple keyword rules or word counts cannot.
When patterns are too complex for manual features
Sometimes the issue is not the data format but the pattern itself. Recommendation systems, fraud detection, ranking, personalization, and anomaly detection can involve many signals interacting in ways that are hard to define by hand.
Deep learning becomes more attractive when feature engineering has clearly hit a limit. A common mistake is jumping to deep learning before building a baseline; without that baseline, it is hard to know whether the added complexity improved anything.
When you have enough data and computing power
Deep learning needs support around it, not just an interesting dataset. Before choosing it, check three things: whether you have enough relevant examples, whether training and retraining costs are acceptable, and whether the result can be monitored once it is in use.
- Good fit: large, relevant dataset; complex input; clear value from higher performance.
- Weak fit: small dataset; strict explainability needs; limited compute or engineering support.
- Sensible first step: build a simpler baseline, then move deeper only if the baseline is not good enough.
Conclusion
Machine learning is usually the better first choice when your data is structured, your team needs speed, and the decision must be easy to explain. Deep learning is the stronger option when the problem depends on images, speech, video, large text, or patterns too complex to design by hand. The smartest choice is rarely "use the most advanced model"; it is to use the simplest approach that solves the problem reliably, then add complexity only when it earns its keep.